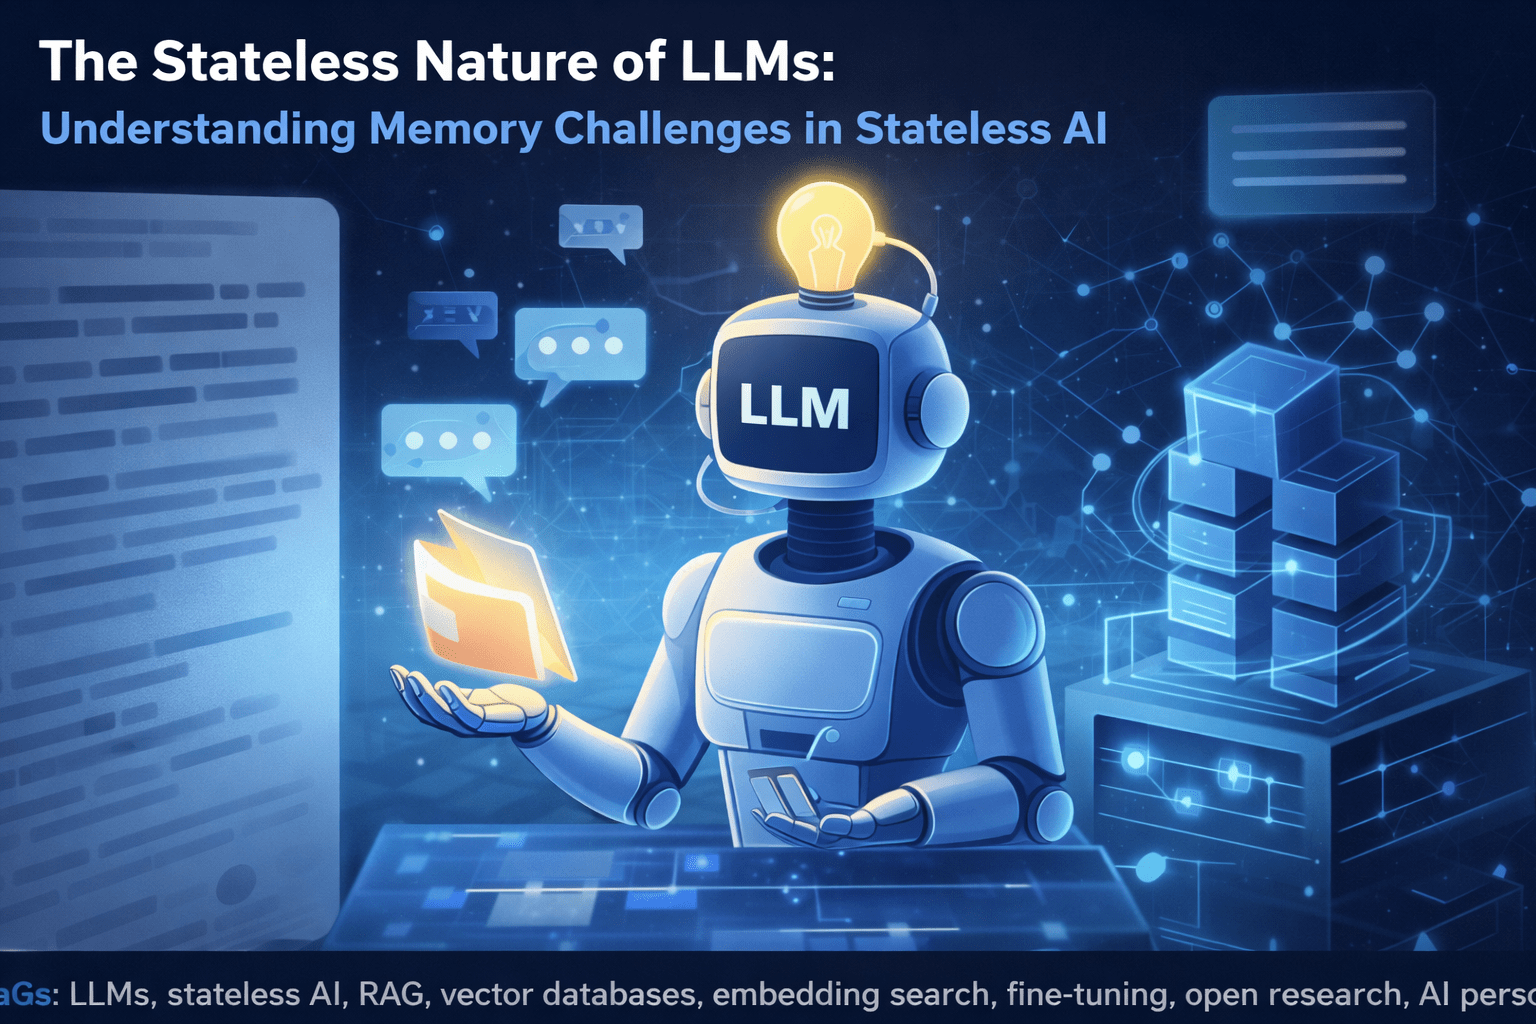
Abstract. Large Language Models (LLMs) are, by architecture, stateless between inference calls. Each conversation begins with a blank slate, retaining no trace of prior interactions. This article examines the technical roots of this limitation, surveys the landscape of engineering workarounds — from retrieval-augmented generation to vector databases and fine-tuning — and discusses the open research challenges that remain. It is written for engineers, researchers, and technically minded practitioners who want a rigorous, end-to-end understanding of the memory problem in modern AI systems.
1. The Stateless Nature of LLMs
At the core of every transformer-based LLM is a deceptively simple contract: given an input sequence (the context window), produce a probability distribution over possible next tokens. The model applies a fixed set of learned weights — billions of parameters — to that input, and returns a result. Then it stops. There is no hidden state, no accumulating register, no mechanism that carries information forward to the next request.
This is not a design oversight. It is a deliberate consequence of the transformer architecture, which processes all input tokens in parallel and derives representations through self-attention across the entire sequence. The "memory" a model appears to have within a conversation is entirely contained within the context window passed to it on each call — nothing more.
When a conversation ends, the context window is discarded. When a new conversation begins, the model starts from zero. Any sense of continuity a user experiences across sessions is an illusion produced by the application layer — not by the model itself.
1.1 What the Model Actually "Knows"
It is important to distinguish two different kinds of model knowledge:
- Parametric knowledge: information encoded into the model's weights during pretraining and fine-tuning. This is fixed at inference time and includes facts, reasoning patterns, language understanding, and world knowledge up to the training cutoff.
- In-context knowledge: information presented in the current input prompt — the conversation history, injected documents, retrieved passages, or tool outputs. This is ephemeral; it lasts only as long as the context window.
Persistent memory, in the true sense, requires neither — it requires a mechanism for storing and retrieving information across inference calls. LLMs lack this natively.
2. Why This Matters in Practice
The stateless design creates a set of real-world problems that product teams and researchers must actively work around:
- User context loss: A model cannot recall that a user prefers concise answers, works in a particular industry, or has an ongoing project. Every session requires re-establishing context.
- Knowledge staleness: Parametric knowledge has a hard cutoff. Events, facts, or documents that postdate training are simply unknown to the model unless injected into the context.
- Context window limits: Even within a single session, models have finite context lengths — ranging from thousands to hundreds of thousands of tokens depending on the model. Long conversations eventually overflow, causing the model to "forget" earlier exchanges mid-session.
- Personalization at scale: Building AI assistants that feel personalized requires maintaining per-user state across millions of interactions — a non-trivial infrastructure and privacy challenge.
3. Engineering Solutions: A Taxonomy
The AI engineering community has developed a rich toolkit for approximating memory in stateless models. These approaches exist on a spectrum from simple to architecturally complex.
3.1 Context Window Injection
The most direct approach is to serialize relevant past information into the prompt on each call. This might include a conversation summary, user profile, or relevant facts retrieved from storage. It requires no model changes and works with any LLM.
Strengths: Simple, universally compatible, no training required.
Limitations: Bounded by context length. As histories grow, injection becomes expensive (in tokens and cost) or lossy (requiring aggressive summarization). It also places the burden of retrieval and formatting entirely on the application layer.
3.2 Retrieval-Augmented Generation (RAG)
RAG is the dominant paradigm for giving LLMs access to external knowledge at inference time. At its core, it combines a retrieval system (typically a vector database) with a generative model. When a query arrives:
- The query is encoded into a dense vector embedding.
- The vector store is searched for semantically similar passages.
- Top-k results are injected into the prompt as context.
- The model generates a response grounded in that retrieved context.
RAG effectively separates knowledge storage (a database) from knowledge application (the model), enabling the knowledge base to be updated independently of the model itself. It is widely used in enterprise applications, chatbots grounded in documentation, and long-horizon research assistants.
Key technical considerations: Chunking strategy, embedding model quality, retrieval ranking (dense vs. sparse vs. hybrid), context length limits, and hallucination risk when retrieved passages are irrelevant.
3.3 Vector Databases and Semantic Memory
Vector databases — systems like Pinecone, Weaviate, Qdrant, and pgvector — provide efficient approximate nearest-neighbor (ANN) search over high-dimensional embedding spaces. They are the enabling infrastructure for RAG and for any system that stores episodic memory ("what did this user tell me last Tuesday?") in a retrievable form.
The architectural pattern for episodic memory typically looks like this: after each conversation turn, key entities, preferences, or facts are extracted, embedded, and upserted into a per-user namespace in the vector store. On subsequent turns, the user's query triggers a retrieval pass before generation, effectively "remembering" relevant prior interactions.
3.4 Summarization and Compression
For long in-session conversations that risk overflowing the context window, a common pattern is recursive summarization: older turns are compressed into a rolling summary by a secondary model call, and that summary is prepended to the active context. This is often called a "memory buffer" pattern.
More sophisticated variants apply importance weighting — retaining verbatim exchanges that are deemed critical (e.g., explicit user preferences or key decisions) while compressing routine back-and-forth.
3.5 Fine-Tuning and Continued Pretraining
Fine-tuning adapts a base model's weights on a curated dataset, effectively baking new knowledge or behaviors into the model itself. This is sometimes proposed as a memory solution — "just fine-tune the model on the user's data" — but it has severe practical limitations:
- Fine-tuning is computationally expensive and operationally complex.
- It suffers from catastrophic forgetting: new training can overwrite prior knowledge.
- It cannot be easily undone or updated at the granularity of individual facts.
- It encodes knowledge statically — there is no mechanism for the model to "unlearn" stale information.
Fine-tuning is better understood as a tool for adapting style, format, or domain expertise, not for dynamic, per-user episodic memory.
3.6 Platform-Level Memory Systems
Commercial AI products — including Claude, ChatGPT, and Google Gemini — have introduced platform-managed memory layers that abstract away the technical details from end users. These typically work by: extracting salient facts from conversations using a secondary model pass, storing them in a structured personal store, and injecting them into future sessions automatically.
These systems represent an important usability milestone, but they still operate on the same fundamental principles: external storage plus context injection. The underlying models remain stateless.
4. Open Research Challenges
Despite significant engineering progress, several hard problems remain unsolved:
4.1 The Write Problem
Current systems are good at reading from memory (retrieval) but struggle with writing to memory intelligently. What should be stored? How should it be organized? How should contradictory information be reconciled? When should facts be forgotten or invalidated? These are open problems that require reasoning, not just retrieval.
4.2 Scalability and Cost
Injecting retrieved context into every request adds latency and token cost. At scale — millions of users, billions of interactions — this is non-trivial. Efficient compression and selective retrieval remain active research areas.
4.3 Privacy and Trust
Persistent memory systems must grapple with consent, data ownership, and the right to be forgotten. Who controls what the AI remembers? Can users inspect and edit their memory? What happens when users share a device? These are not merely technical questions but ethical and regulatory ones.
4.4 Memory-Augmented Architectures
A more fundamental research direction asks: can we build neural architectures with native, trainable memory mechanisms that go beyond the context window? Work on memory-augmented neural networks, neural Turing machines, and external memory attention points in this direction, but none have yet matched the scale or capability of transformer-based LLMs.
4.5 Continual Learning
The ultimate goal — a model that learns continuously from its interactions, updating its weights in real time without catastrophic forgetting — remains largely aspirational. Progress in continual learning, elastic weight consolidation, and gradient episodic memory offers partial solutions, but robust, production-grade continual learning at LLM scale is an unsolved challenge.
5. Conclusion
The memory problem in LLMs is not a single technical gap but a family of interrelated challenges spanning architecture, infrastructure, usability, and ethics. Today's best solutions — RAG pipelines, vector databases, platform memory layers — are effective engineering workarounds built on top of fundamentally stateless models.
This distinction matters. It means that improvements in "AI memory" today are largely improvements in external systems: better retrieval, smarter compression, more capable embedding models. The LLM itself is unchanged.
The more fundamental challenge — building AI systems that learn, remember, and forget in the way humans do, across timescales ranging from a single conversation to years of accumulated experience — is one of the defining open problems of the field. Its resolution will require advances not just in software engineering, but in the core theory of how intelligence stores and retrieves knowledge.
This article is intended for technical practitioners. Architectural details reflect the state of the field as of March 2026.