There is a version of the "sovereign AI" argument that is easy to nod along to and impossible to act on. It imagines an African continent that builds its own frontier laboratories, trains its own trillion-parameter models, fabricates its own chips, and competes head-to-head with the firms that currently sit at the commanding heights of the industry. Stated that way, the idea collapses on contact with reality, the capital, compute, and energy gaps are simply too large.
But that is a strawman, and treating it as the real proposal does a disservice to a serious case. The genuine question is not whether Africa should pursue sovereignty in artificial intelligence. It is which kind of sovereignty is achievable, where it actually pays off, and what it would take to win it. Answer that precisely, and the case stops being aspirational and becomes a strategy.
The word is doing too much work
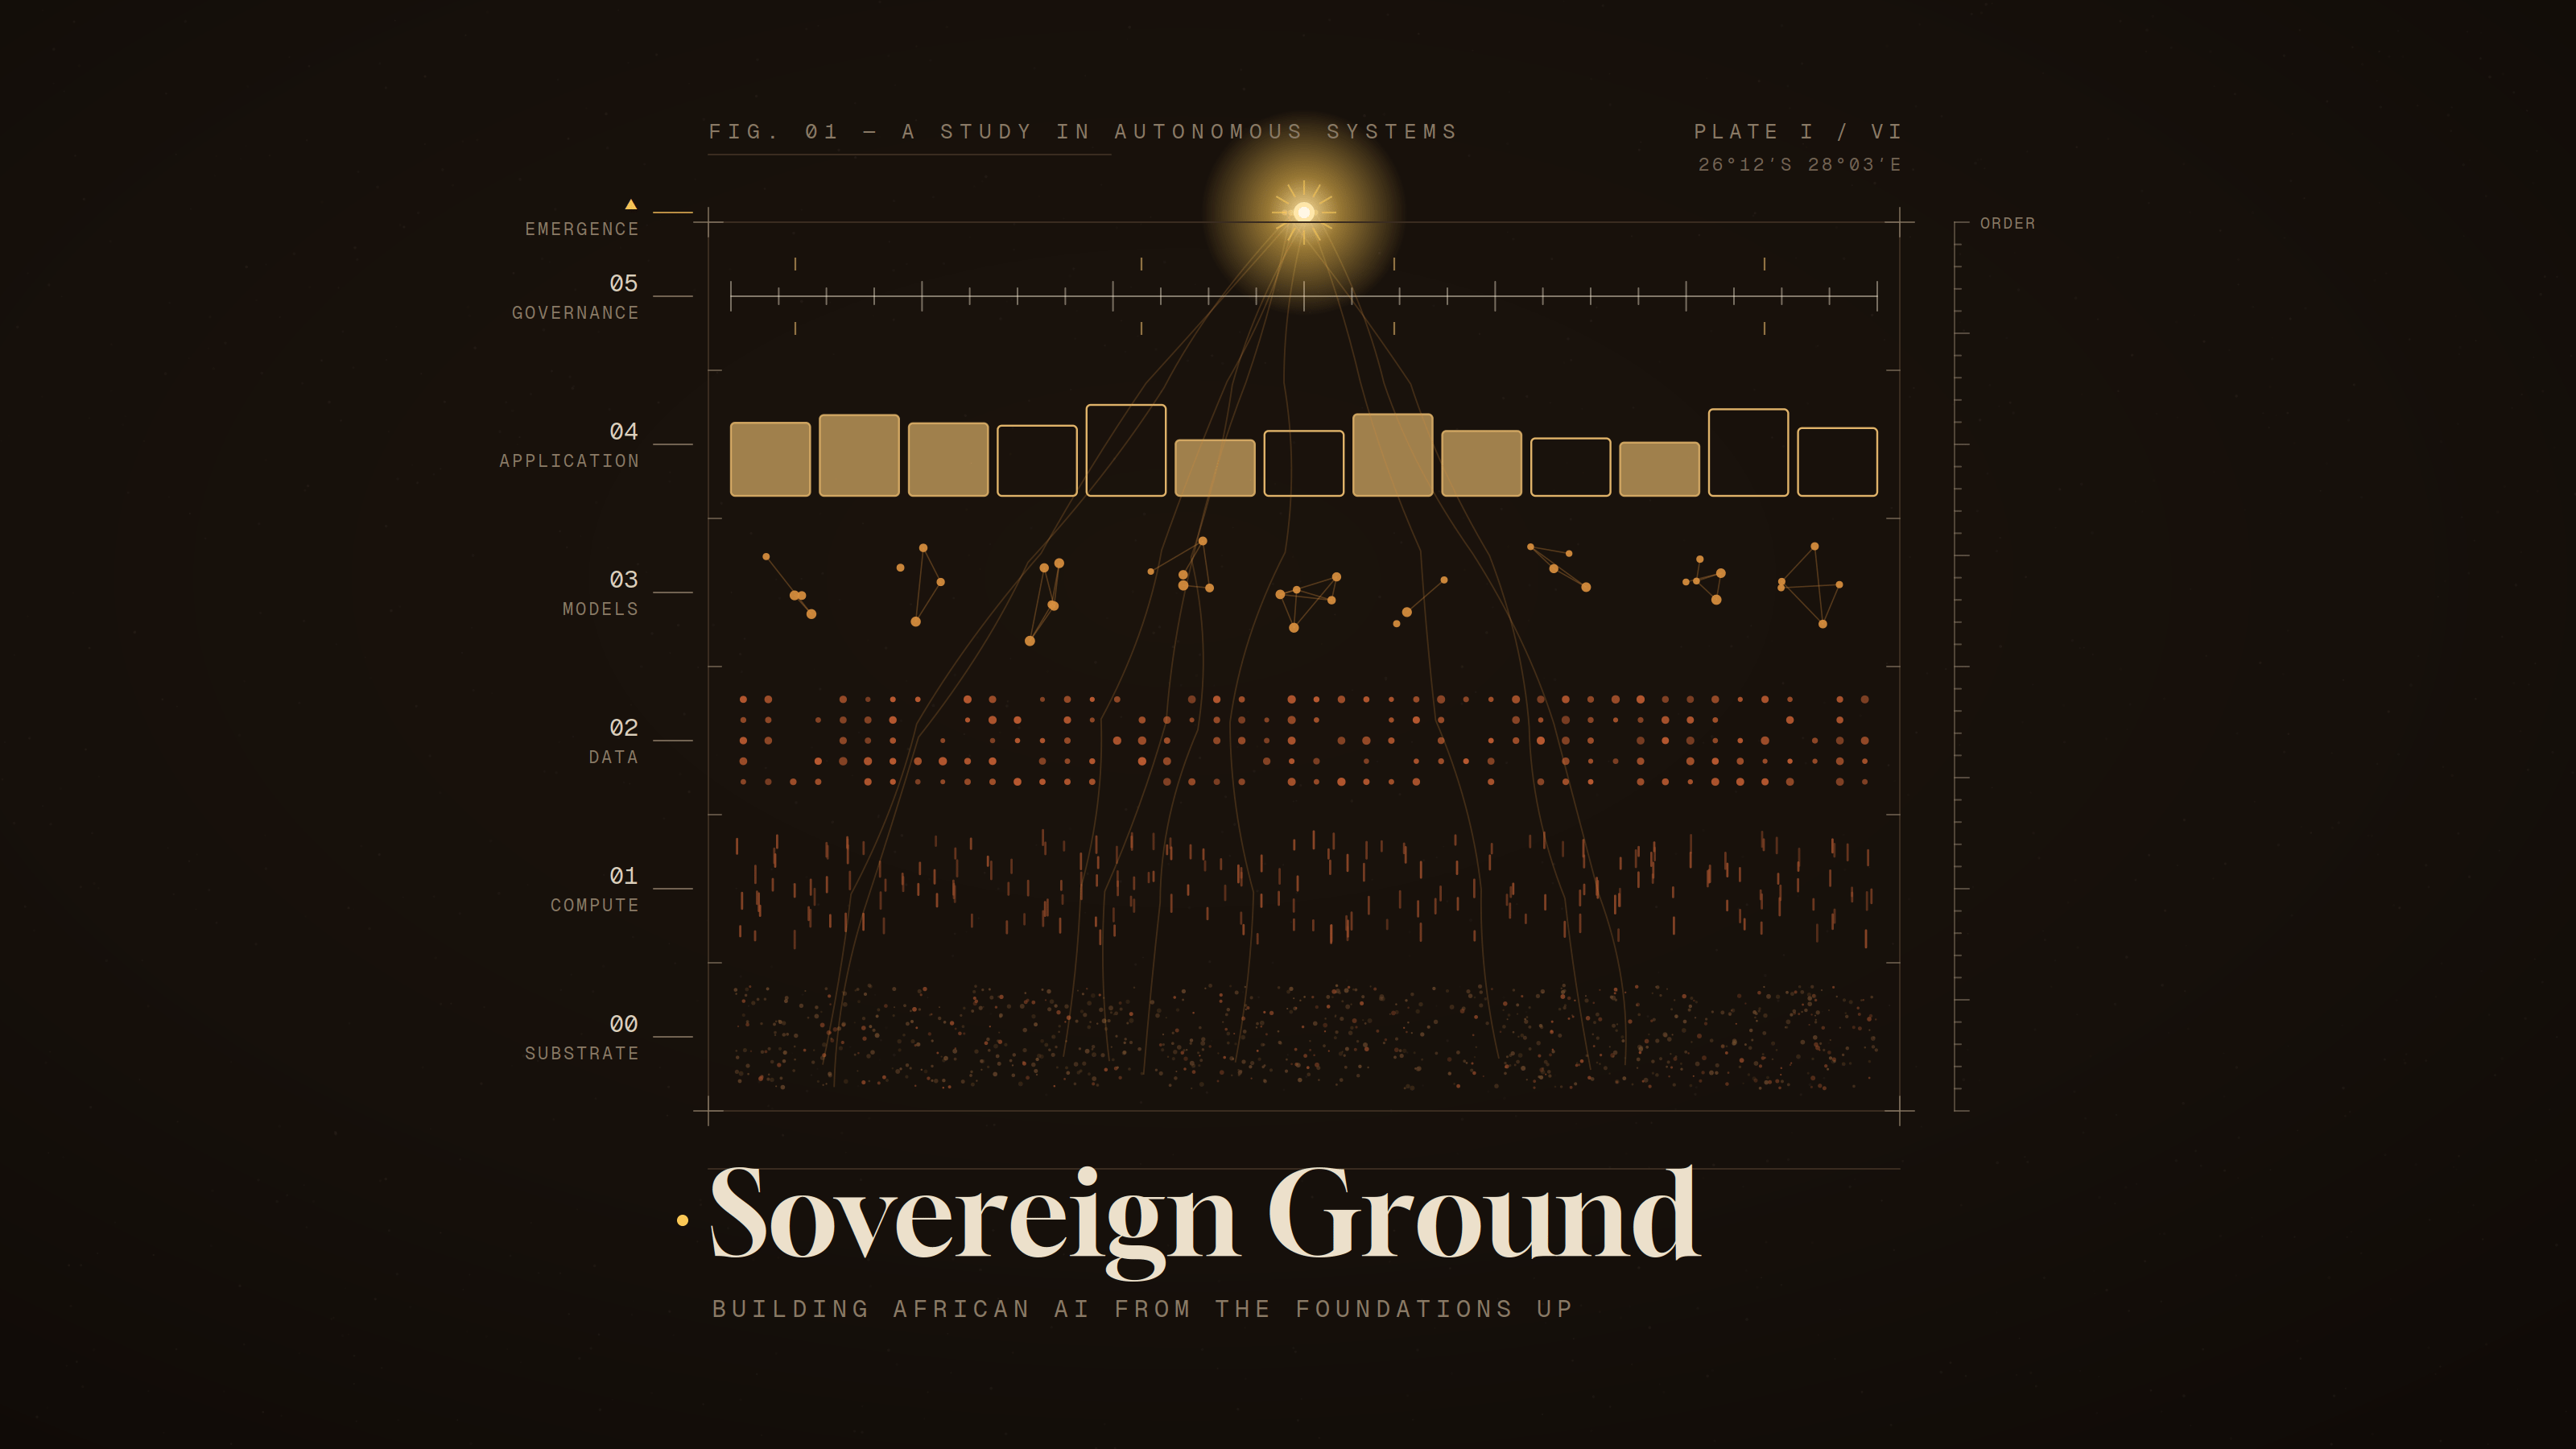
"Sovereign AI" gets used to mean everything from "we own the data centres" to "we have a national chatbot." Before the debate can be productive, the term has to be disaggregated into a stack:
- Compute - the chips, data centers, and power to train and run models.
- Data - the corpora, governance regimes, and ownership rights over information generated on the continent.
- Models - foundational and domain-specific systems, and the talent to build and adapt them.
- Applications - the products that actually reach citizens, firms, and governments.
- Governance - the rules, standards, and norms that decide how all of the above may be used.
Full-stack sovereignty, owning all five domestically, is the version that fails the realism test. Selective sovereignty, owning the layers where context concentrates value and where the capital barrier is lowest, is the version worth pursuing. Almost every strong argument for African AI is really an argument about the data, application, and governance layers. Almost every weak argument is one that quietly assumes the compute layer. Keeping those apart is the whole game.
The part of the case that is unanswerable
The most durable argument has nothing to do with technology and everything to do with political economy. In the current arrangement, most of the value in AI is captured at the foundation-model layer, which is held by a small number of firms in two countries. That leaves much of the world, Africa prominently among it, occupying two roles: the super-user, consuming systems built elsewhere, and, more uncomfortably, the input.
The second role is not a metaphor. A great deal of the human labour that makes modern AI usable, data annotation, reinforcement-learning feedback, content moderation, has been routed through low-wage centres, with Nairobi among the best-documented hubs. This is the means-of-production point in concrete form: a continent supplying the raw human judgment that trains the models, while the models, the margins, and the intellectual property accrue elsewhere.
You do not need a particular ideology to find this arrangement strategically unwise. Any region that consumes a general-purpose technology without shaping it inherits dependencies it did not choose and cannot easily exit. That is reason enough to want a seat at the table that is more than a stool in the data-labelling room.
The strongest practical lever: context and language
If agency is the why, context is the where. This is the layer where local builders have a structural advantage that no amount of capital elsewhere can erase.
African languages are severely underrepresented in the data that trains today's dominant models. Hundreds of languages spoken by hundreds of millions of people have a thin or nonexistent digital footprint, and models trained overwhelmingly on Western corpora perform measurably worse on them. The consequences are not academic. A model that mishandles a language, misreads a name, misunderstands a local legal procedure, or fails to recognise a regionally common crop disease or health condition is not a neutral tool, it is a tool optimised for someone else's reality.
Community efforts such as the Masakhane network have spent years demonstrating both the size of this gap and what closing it looks like, by building open language resources and models for African languages from the ground up. The lesson is encouraging for the strategic argument: this work delivers real, near-term value, and it does not require frontier-scale compute. You close the context gap with good data, domain expertise, and efficient fine-tuning, not with a billion-dollar training run. The layer where Africa has the most to gain is the same layer where the barriers to entry are lowest. That alignment is the single most important fact in the entire debate.
The argument that needs rewriting: capital and compute
Here is where enthusiasts tend to overreach, and where intellectual honesty matters most. It is sometimes claimed that sovereign systems can sidestep prohibitive capital entirely, that by focusing on the structure of information and on causality rather than on brute-force scale, local developers can build effective AI without the budgets of the global giants. There is a real insight buried in this, and a real error layered on top of it.
The insight: not every problem requires a frontier model. Smaller, specialised, and causally-grounded systems can outperform giant general-purpose ones on narrow, high-value tasks, often at a tiny fraction of the cost. For diagnosing a specific class of crop disease, routing agricultural credit, or triaging clinic intake in a particular language, a focused model beats a generic colossus. Methodological cleverness genuinely substitutes for scale in many domains that matter to African economies.
The error: cleverness does not abolish infrastructure. Even modest models require compute to train and serve, and compute requires chips, data centres, and, the binding constraint across much of the continent, reliable, affordable power. "Without billions" is true for the application and fine-tuning layers. It is not true for the compute layer, and pretending otherwise sets builders up to be blindsided by an electricity bill rather than an algorithm.
The honest reframing is this: Africa should not try to win where capital intensity is highest. It should compete fiercely where methodological insight and local context substitute for capital, and it should treat compute as shared infrastructure to be financed regionally and pragmatically, including through partnerships, rather than as a sovereignty test to be passed alone.
The quietly decisive layer: who owns the data
Sitting underneath all of this is a question that rarely makes the headline but largely determines the outcome: who owns and governs African data?
If the information generated by African citizens, hospitals, markets, and governments flows freely offshore to train models that are then sold back at a premium, no amount of local model-building reverses the underlying dependency. Conversely, sound data-governance regimes, building on instruments like the African Union's Malabo Convention on cyber security and personal data protection, and on national frameworks, turn data from an extracted raw material into a governed strategic asset. Data sovereignty is less glamorous than building a national model, but it is more foundational, because it sets the terms on which every other layer operates.
Going it alone is the wrong unit of analysis
Much of the sovereignty conversation is framed nation by nation, and that framing quietly imports the realism problem. Few individual African states can independently finance competitive compute, retain enough specialised talent, or assemble data at useful scale. Pooled at a regional or continental level, the same resources start to look viable. Shared compute facilities, common data-governance standards, joint talent pipelines, and interoperable language resources are the kind of thing that is unaffordable for one country and rational for a bloc. The realistic unit of sovereignty is cooperative, not national — and the sooner the strategy reflects that, the less it has to pretend.
A caution belongs here too. "Sovereignty" is a flexible word, and it can be invoked to justify protectionism or state control over information without actually producing capability. Sovereign AI is only as good as the openness and institutions behind it. A walled garden with a flag on it is not the goal.
The clock that is actually running
Finally, there is timing. The rules of the road for AI, standards, safety norms, governance frameworks, the terms of international cooperation, are being written now. Regions absent from those rooms do not get a neutral outcome; they get frameworks designed around other contexts and applied to theirs. Contributing meaningfully to the global discourse is the difference between shaping the constraints you will live under and inheriting them.
The sovereignty worth winning
Strip away the maximalist version, and a coherent strategy emerges. Africa should not chase frontier parity, because that is where its disadvantage is largest and the relevance of winning is smallest. It should instead claim the layers where context concentrates value and capital requirements are lowest: language and domain models, the applications that reach real users, the governance of its own data, and a real voice in the rules. It should treat compute as shared, financed infrastructure rather than a solitary test of pride, and it should organise the whole effort regionally rather than country by country.
That is not a retreat from sovereignty. It is the only version of it that can actually be built, and, not coincidentally, the version that delivers the most for the people it is meant to serve. The choice in front of the continent is not between dependence and an impossible self-sufficiency. It is between being a permanent super-user of someone else's intelligence and becoming the author of the parts that matter most.





